High-volume workloads
Keep success rates high and concurrency reliable as your request volume grows.
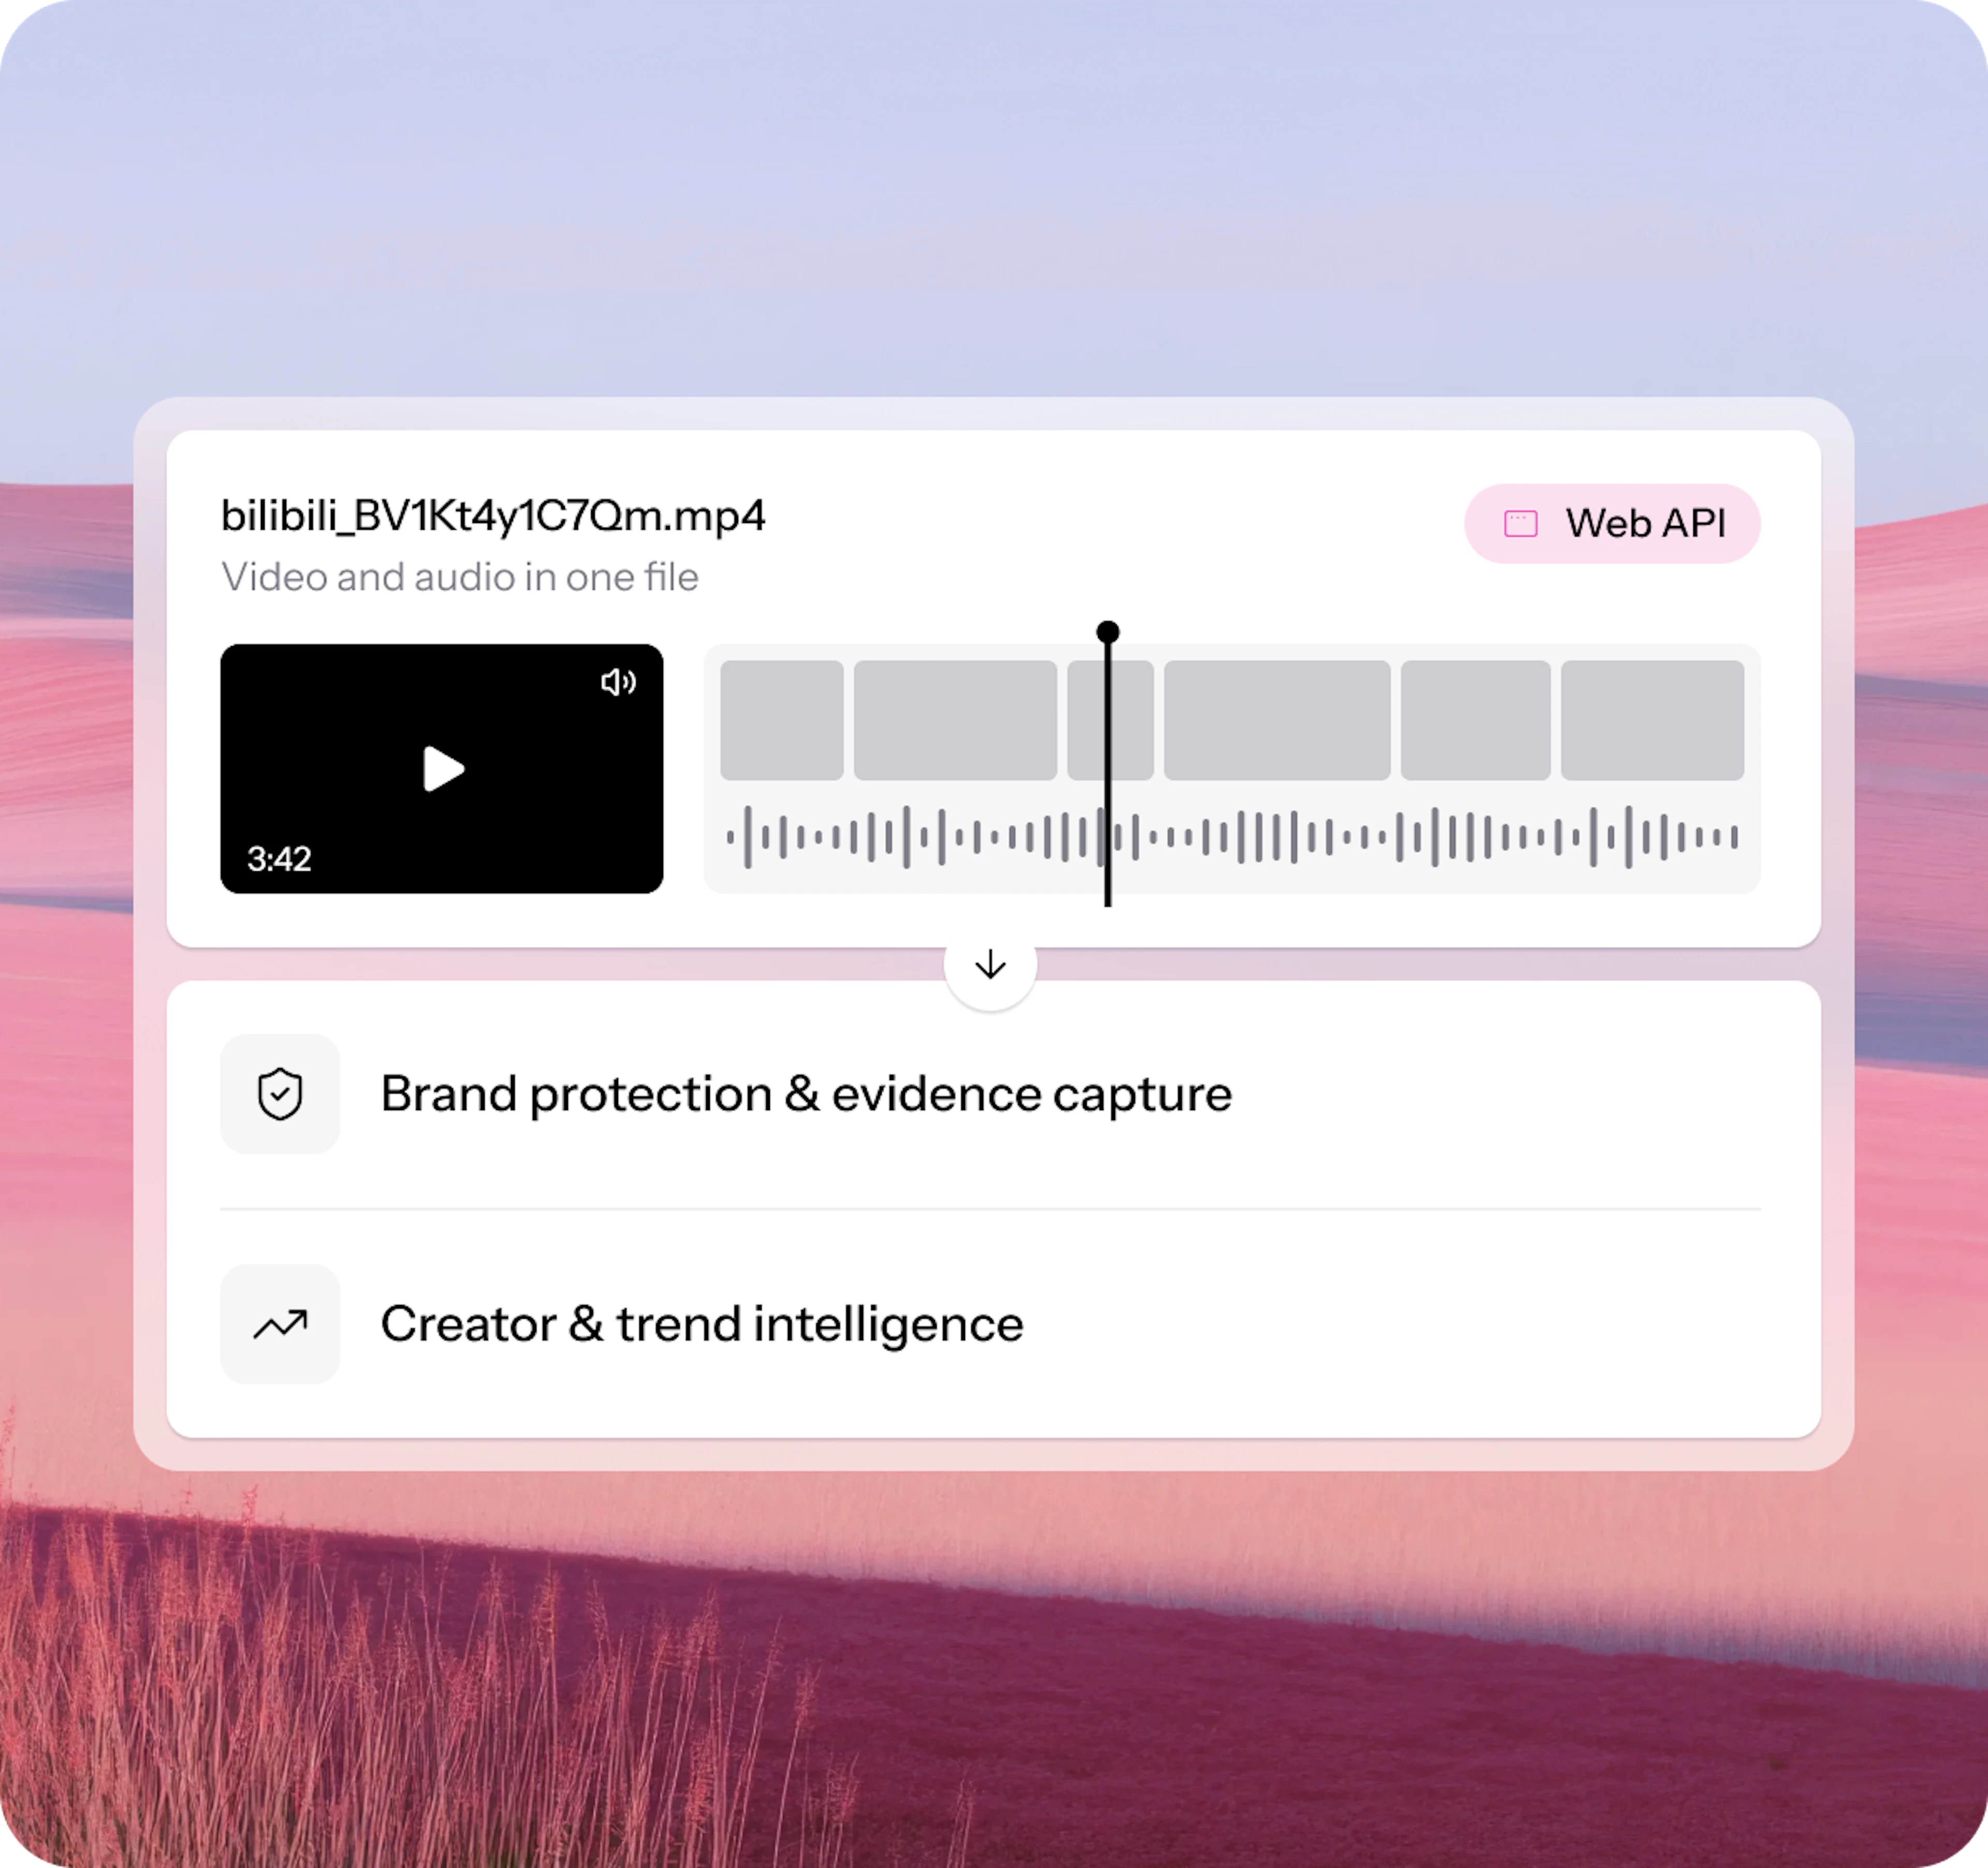
Collect public video and audio data from Bilibili and other video platforms with Web API. Get structured, ready-to-use output to power multimodal AI and computer vision intelligence.
Engineered for AI and intelligence pipelines
Data lands directly in your storage, no extra steps
More video data sources within reach
* Part of Web API product
Trusted by 15,000+ clients globally


Web API’s Scrape endpoint lets you collect publicly available video data from Bilibili and other websites with one request. Using asynchronous delivery, you can submit a single job or a batch. Access management and geo-targeting are handled for you.
Step 1: Get your API key. Create a Web API instance in the Oxylabs dashboard and copy your API key.
Step 2: Send your request. Add your endpoint URL, payload, and user credentials, and send it to our API. We’ll take it from there!
Step 3: Receive the result. The API supports video and audio data downloading from popular video platforms, as well as channel data, video subtitles, and metadata retrieval.
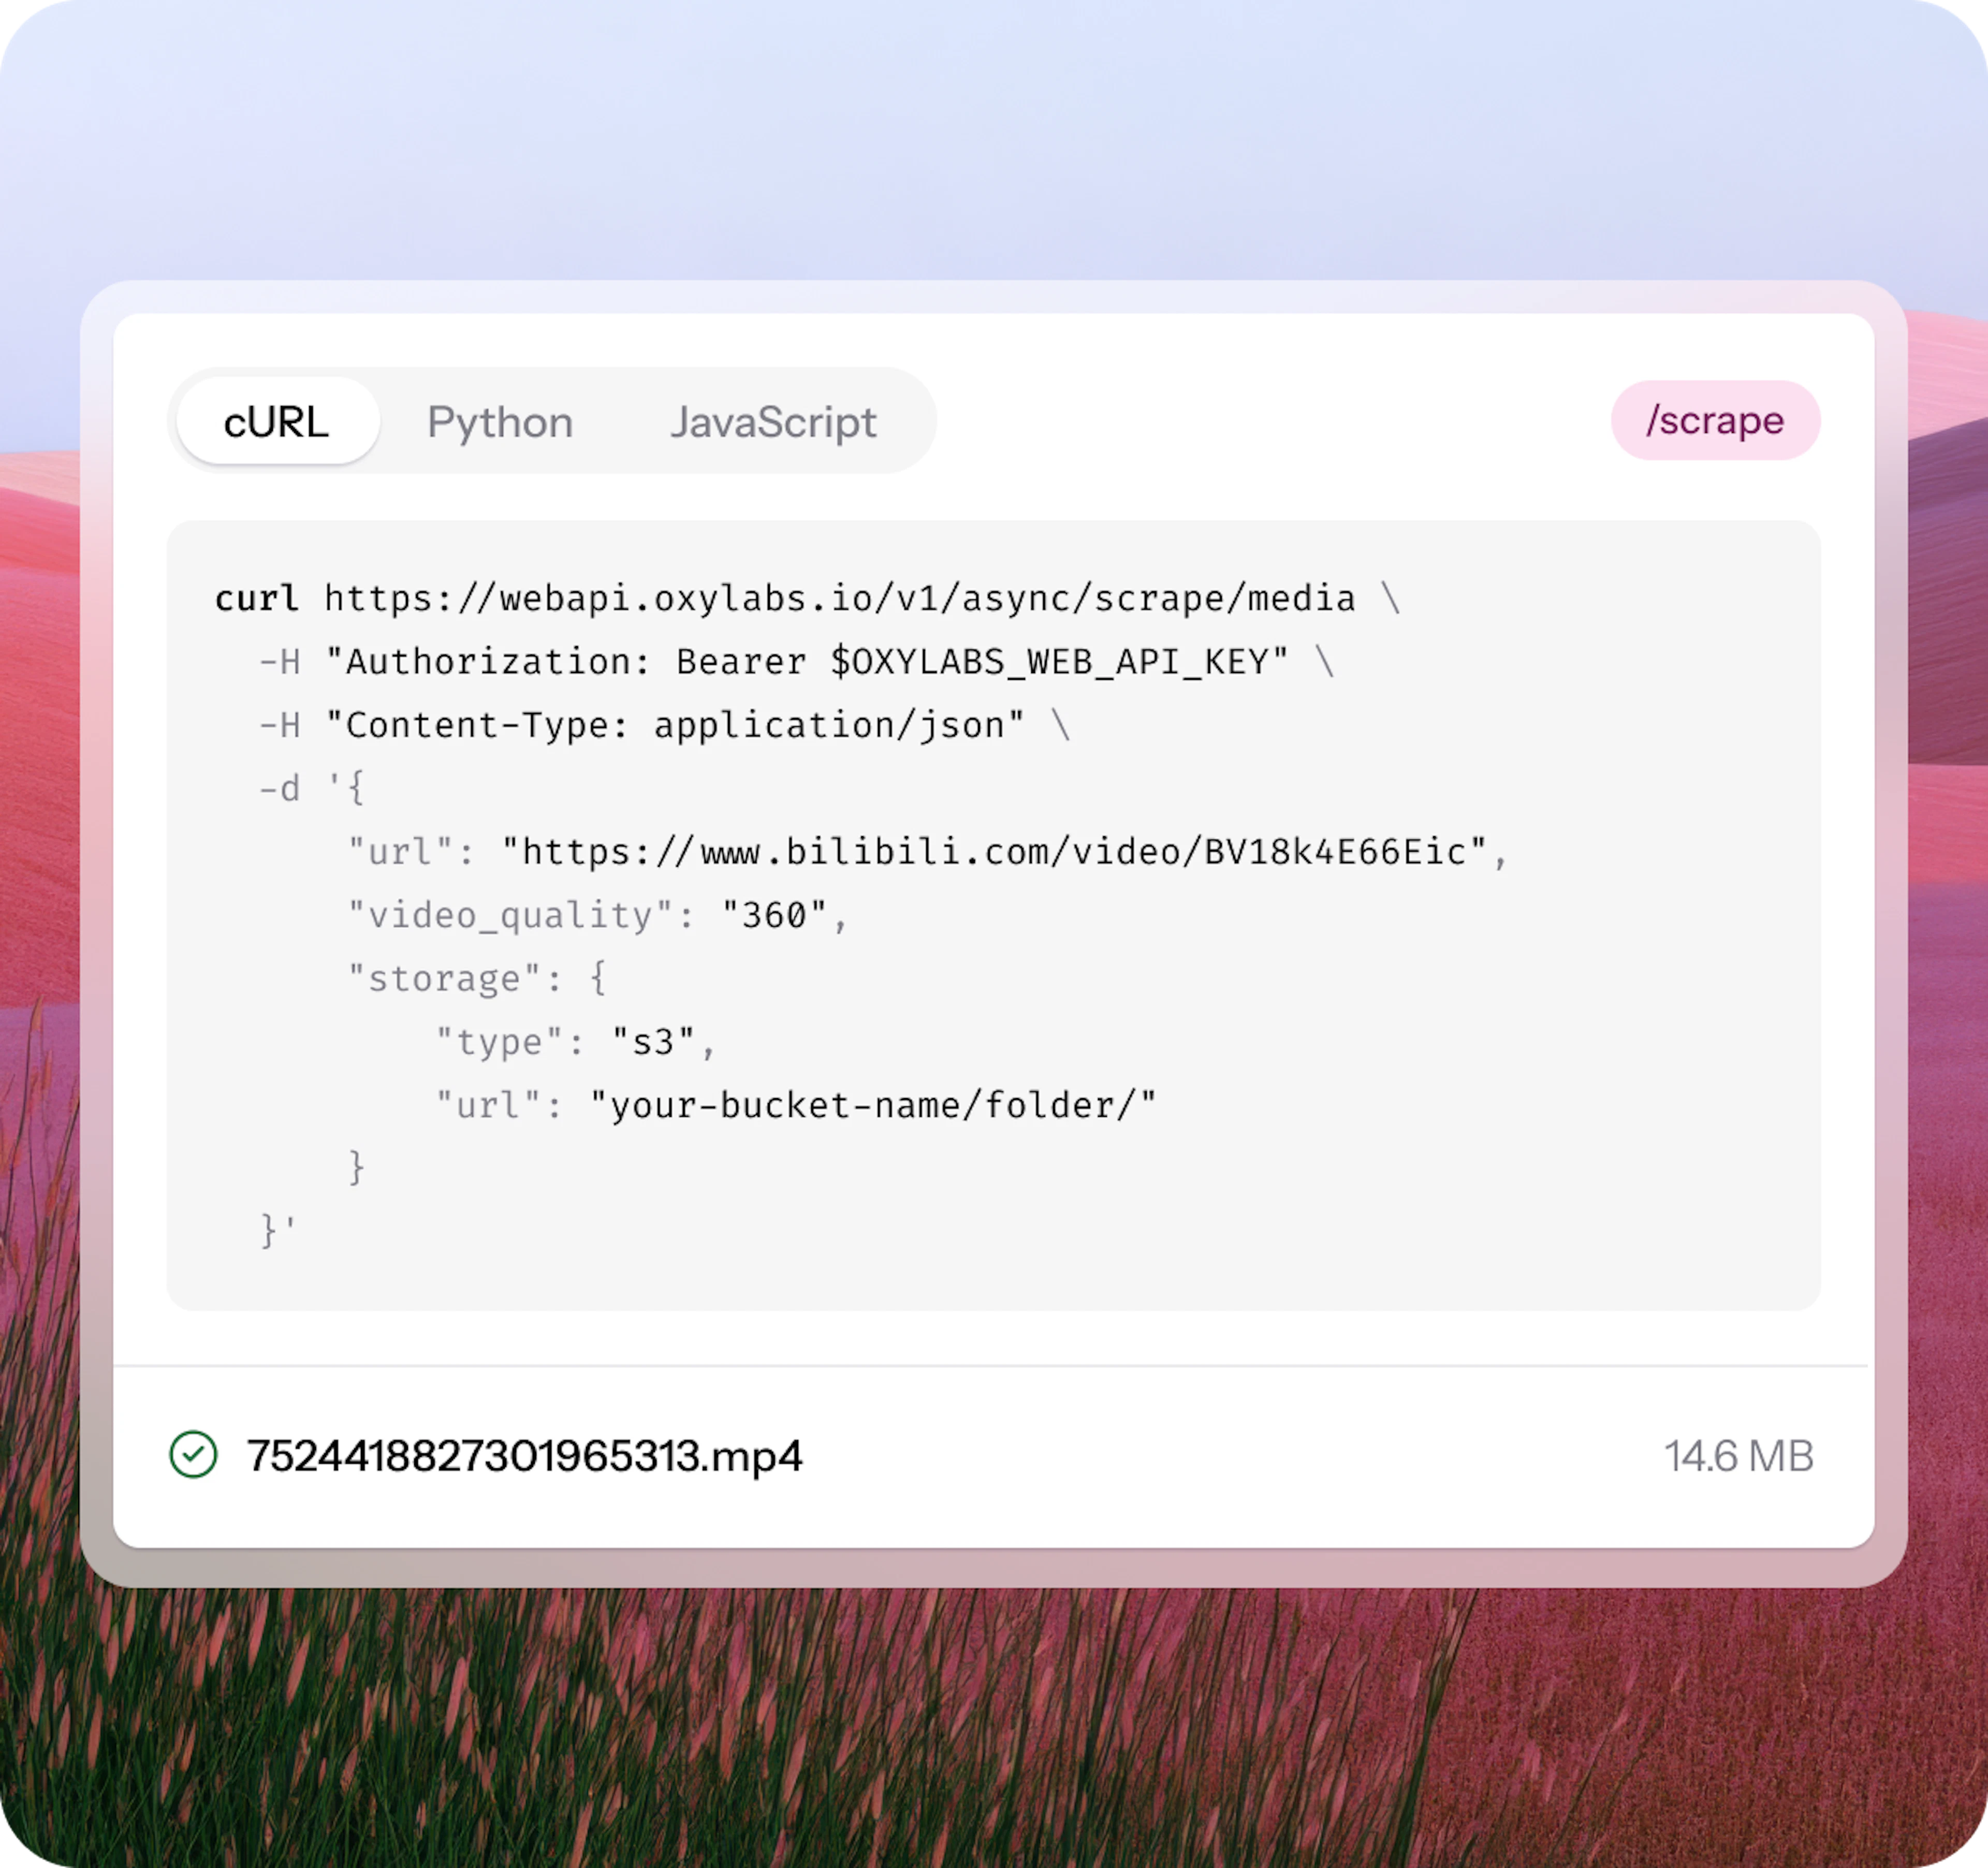
Scrape Bilibili for public data with fully managed infrastructure.
High-volume workloads
Keep success rates high and concurrency reliable as your request volume grows.
Agent-native by design
Connect agents through MCP and Agent Skills, with token-efficient output.
Enterprise-grade infrastructure
Run on certified, dependable infrastructure, backed by a decade of production expertise.
99.9% API uptime
Rely on high success rates and fast response times for steady data collection.
11+ years of expertise
Get consistent data delivery as your volume grows, on infrastructure refined over a decade.
177M+ proxies in 195 countries
Collect accurate, localized public data from your chosen locations.
Whether you’re running your first request or scaling to millions, our team is here to help.
24/7 live chat: get all your questions answered here and now.
Comprehensive documentation: explore our guides and an interactive Playground to test requests before you build.
Scaling opportunities: share your use case for a setup built around your needs.
Discover relevant public video pages from a query, so you don’t need to know every URL in advance.
Get ranked results with video titles, descriptions, and URLs
Localize results with country-level targeting and receive clean JSON
Add a site: filter and indicate the target in your query for the most accurate video links
Send the URL of a public Bilibili video page, or of any other public site, and get the data back in the format you need.
Unlock video data collection at scale
See what’s trending online in real time, in any location
Use MCP Server and Agent Skills for instant AI agent access
Collect Bilibili video data alongside other public sources, and scale
from a free start to enterprise volumes.
Single subscription. All product access.
Welcome credits
FREE
Starter
$15/mo
Basic
$100/mo
Flexible
$500/mo
Enterprise
Custom
/Scrape
From
$0.50/1K res.
Up to 10K results
From
$0.50/1K res.
Up to 30K results
From
$0.45/1K res.
Up to 222K results
From
$0.35/1K res.
Up to 1.43M results
From
$0.25/1K res.
10M+ results
Can't find the plan that suits your business case? Explore more options
Industry-leading success rates
24/7 expert support
Enterprise-grade security & compliance
Real-time spending & usage data
Fast-adapting infrastructure
Scaling with your needs
Bilibili is a Chinese video-sharing platform known for anime, gaming, technology and educational content, much of it user generated content. It is also known for danmaku, comments that scroll across the video while it plays. Its publicly available videos, audio, subtitles, and metadata are a source of content for market research, media analysis, multimodal AI and computer vision development.
It depends on what data you collect, how you collect it and how you use it. Web API is designed for collecting publicly available data. Before you start, review Bilibili’s terms of service and the laws that apply to your project, including copyright, privacy and data protection rules. You are solely responsible for deciding what to collect and for making sure your use complies with applicable laws and Bilibili’s terms of service.
Video and audio content are typically protected by copyright and may require authorization from the content creator, and collecting personal data needs a lawful basis and transparency. We recommend consulting your legal advisor. This is general information, not legal advice.
Web API has two endpoints. /Search helps you discover public video pages, and /Scrape collects page data in Markdown, HTML, JSON or a screenshot. For video, the media endpoint retrieves public video data, together with its audio data, for use in LLMs and AI models.
Scraping public Bilibili data is easy with Oxylabs' Web API. Just copy the URL from any Bilibili page that shows a video and send it to the /media endpoint along with your storage details. Common URL formats are accepted, including standard, embed, and short video page links, so you don't need to clean up links first. The API retrieves the video and uploads it to your Amazon S3, Google Cloud Storage, S3-compatible storage, or TOS bucket. You can also set a callback URL to get notified when the job is finished. For all parameters, see our Media Scrapers documentation.
To collect publicly available video metadata such as the title, uploader, view and like counts, and upload date, send the Bilibili video URL to the /scrape endpoint. The /media endpoint only downloads the video file and doesn’t return this additional data.
Not as a separate file, but you get the audio together with the video. The /media endpoint downloads public videos from Bilibili and other media platforms with their audio included and delivers them to your cloud storage. Please check that you have the right to use the content you collect.
Yes. New users get a $5 welcome credit to try Web API, and you only pay for successfully returned results. Media collection is billed per GB, so check the pricing page for the current rate.
Yes. Web API’s Scrape endpoint can extract data from public websites and a growing set of video and social media platforms, and we’re expanding coverage as demand grows.