
175M+ ethically sourced IPs built for the highest reliability.

High-speed, cost-effective proxies built for any scraping workload.

Premium static residential proxies from trusted ASNs for most difficult targets.

Dedicated IPs from premium ASNs for demanding scraping.

AI-powered proxy solution for optimized web scraping performance.

20M+ IP addresses from real mobile devices for precise targeting.

Free Chrome proxy manager extension that works with any proxy provider.

Free Android proxy manager app that works with any proxy provider.

Free community-driven tools to improve your web scraping projects.

Web Scraper API
All-in-one web data collection platform for every stage of web scraping.

Fast Search API
Ultra-fast organic search results scraper tailored for AI workflows.

Headless Browser
Advanced browser automation solution for AI agents and scraping.

AI Studio
A suite of AI-powered tools for various scraping projects.


Documentation
All features, parameters, and integration details, backed by code samples in every coding language.
Tutorials, samples, and guides.
Latest fixes and features.


Semantic Chunking: How to Split Text for Better RAG Retrieval
Shinthiya Nowsain Promi
2026-09-15
8 min read
 AI Summary:
Splitting a document into chunks decides what a RAG pipeline actually retrieves, and getting it wrong quietly wrecks answer quality. This guide covers how semantic chunking works, how to build it in Python with LangChain or LlamaIndex, and whether the extra computational cost is worth it for your RAG system.
Semantic chunking is a text-splitting method that groups sentences by meaning instead of by a fixed character count, so each resulting chunk stays on a single topic. In a retrieval-augmented generation (RAG) pipeline, how you cut a document into chunks decides what an LLM actually sees when it answers a question – sloppy chunks mean sloppy retrieval, no matter how good the model is. This guide covers how semantic chunking works, how to build a semantic chunker in Python with LangChain or LlamaIndex, and whether the extra compute is worth it for your RAG system.
What is semantic chunking?
A semantic chunker splits a document by meaning rather than length. Instead of counting to 500 characters and cutting mid-sentence, it measures how semantically similar neighboring sentences are and only cuts where the topic actually shifts, so it ends up creating meaningful chunks based on where ideas actually begin and end rather than an arbitrary character count. The output is a set of semantic chunks – passages that each cover one idea, sized however long that idea happens to run.
This matters because retrieval-augmented generation depends on context. A RAG system converts each chunk into embeddings, stores those embedded chunks in a vector database, and at query time retrieves the chunks closest to the user's question before handing the most relevant chunks over to large language models for generation. Whatever the retrieved chunks contain is the entire context window the LLM has to work with for that answer – there's no going back to reread the source document mid-response. If a chunk splits mid-argument or crams three unrelated topics into one section, retrieval returns weak or irrelevant context, and the LLM answers from evidence that doesn't actually support the query. The chunking method is a data quality problem as much as a modeling one – get chunk boundaries wrong and no amount of prompt engineering fixes it downstream. It's one of the more common root causes behind ungrounded answers; our guide to data grounding covers the broader picture of what keeps an LLM's output tied to real evidence.
How does semantic chunking work?
A semantic chunker moves through four steps to turn long documents into multiple chunks that each stay semantically coherent on their own. The exact library differs, but this is the chunking process happening under the hood in LangChain, LlamaIndex, and most other implementations.
Sentence segmentation
The chunker starts by splitting the input document into individual sentences – not chunks yet, just separate sentences, since sentence boundaries are the only structure reliably present in raw text. Some implementations then group a few consecutive sentences into a small buffer before the next step, trading a bit of resolution for noise reduction. Either way, this step turns an entire document into an ordered list ready for embedding – the raw material the rest of the pipeline uses to create chunks in the next three steps.
Embedding generation
Each sentence (or sentence group) passes through an embedding model – a machine learning model trained to represent meaning as numbers, often an open-source sentence transformer such as one from the BGE or MiniLM family, or a hosted option like OpenAI's – which turns the text into a numeric vector capturing its semantic meaning. Sentence pairs end up with similar embeddings when they discuss the same idea, and diverging embeddings when the topic shifts. This is the most computationally expensive step in the whole chunking process, since every sentence needs its own forward pass.
Similarity comparison
With embeddings in hand, the chunker calculates cosine similarity between each pair of consecutive sentences to compare their semantic content. High cosine similarity signals strong semantic similarity – the sentences likely belong to the same idea, while a sharp drop signals a topic change. That gap between two embeddings is often called semantic distance, and most chunkers convert the raw number into a threshold: a hyperparameter you set once and reuse across documents, like the percentile or standard-deviation cutoffs LangChain and LlamaIndex both expose.
Breakpoint detection and chunk formation
Once the semantic distance between two consecutive sentences exceeds the threshold, the chunker marks a breakpoint there and closes the current chunk. Sentences between breakpoints merge back into a single passage, so the final chunks vary in length – a few sentences for a tightly focused paragraph, dozens for a section that stays on one topic throughout. The result is chunk breakpoints that track the document's actual structure instead of an arbitrary character count.
The upshot: semantic chunking replaces a fixed chunk size with one that adapts to how the content is actually organized, preserving the semantic integrity of each idea – smaller chunks where ideas change quickly, larger chunks where a topic runs long.
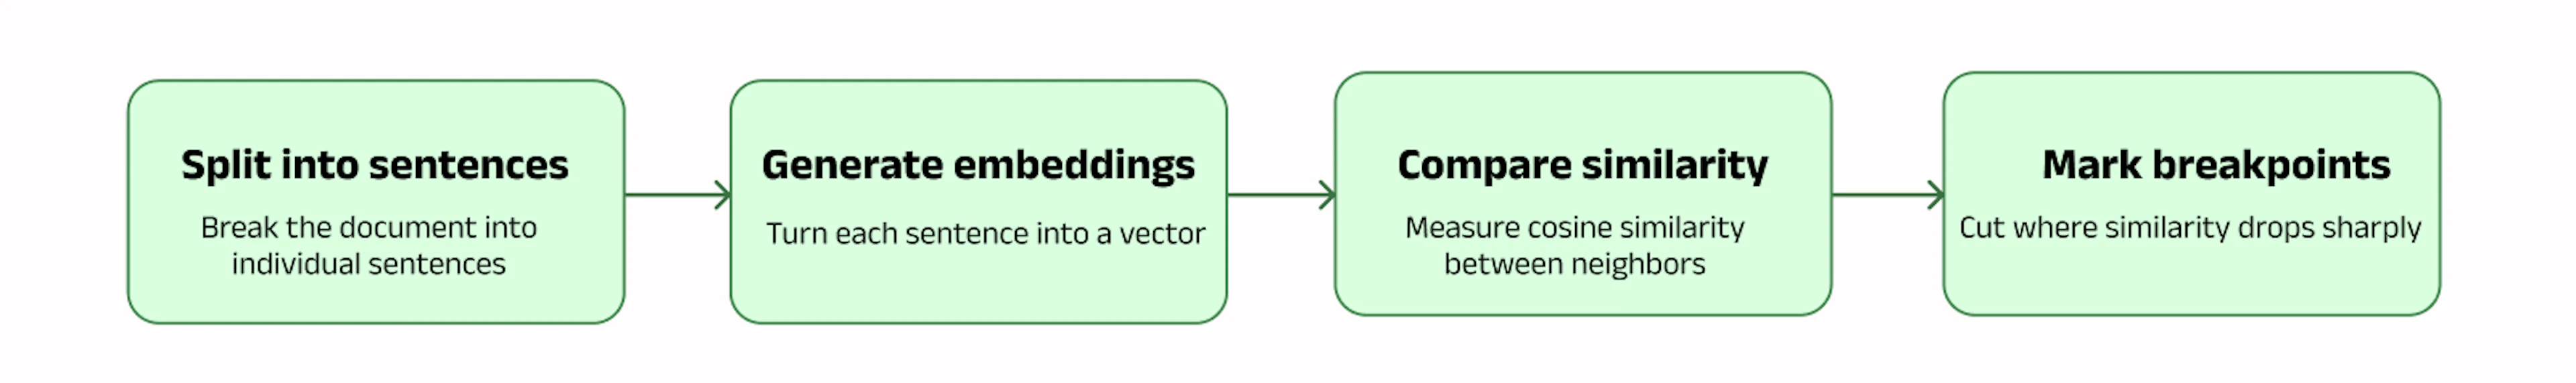
How a semantic chunker splits text
How to implement semantic chunking in Python
Understanding how a semantic chunker works is one thing; implementing semantic chunking in your own pipeline is another. The good news is you don't need to write the similarity math yourself – both LangChain and LlamaIndex ship a semantic splitter out of the box, so building a working chunker comes down to installing a package, picking an embedding model, and setting one or two thresholds. The examples below use OpenAI's embedding model, but any embedding model with a Python client works the same way.
Semantic chunking with LangChain in Python
LangChain's SemanticChunker lives in langchain_experimental and wraps the whole process – sentence splitting, embedding, similarity comparison, breakpoint detection – behind a single class. It's a natural fit if the rest of your RAG pipeline already runs on LangChain.
pip install langchain-experimental langchain-openai

from langchain_experimental.text_splitter import SemanticChunker
from langchain_openai import OpenAIEmbeddings

# Any embedding model works here — this one just needs an OPENAI_API_KEY set
embeddings = OpenAIEmbeddings(model="text-embedding-3-small")

# breakpoint_threshold_type controls how the split threshold is calculated
text_splitter = SemanticChunker(
    embeddings,
    breakpoint_threshold_type="percentile",
    breakpoint_threshold_amount=90,
)

with open("sample_document.txt") as f:
    sample_document = f.read()

# Returns a list of Document objects — each one a semantic chunk
chunks = text_splitter.create_documents([sample_document])

print(f"Split into {len(chunks)} chunks")
print(chunks[0].page_content)
breakpoint_threshold_type sets how the semantic distance threshold is calculated: "percentile" splits at the top X% of distance jumps between sentence pairs, while "standard_deviation" and "interquartile" are less sensitive to a single outlier sentence. Raise breakpoint_threshold_amount and you get fewer, larger chunks, which pushes the average chunk size up; lower it and the chunker produces more, smaller chunks. On a typical article-length document, create_documents returns a handful of chunk embeddings in well under a second once the embedding calls are done.
Semantic chunking with LlamaIndex in Python
If you're already building on LlamaIndex, SemanticSplitterNodeParser does the same job through LlamaIndex's node-based pipeline instead of LangChain's document objects.
pip install llama-index llama-index-embeddings-openai

from llama_index.core import SimpleDirectoryReader
from llama_index.core.node_parser import SemanticSplitterNodeParser
from llama_index.embeddings.openai import OpenAIEmbedding

# Same embedding model family, exposed through LlamaIndex's interface
embed_model = OpenAIEmbedding(model="text-embedding-3-small")

# buffer_size groups sentences before comparing; threshold sets split sensitivity
splitter = SemanticSplitterNodeParser(
    buffer_size=1,
    breakpoint_percentile_threshold=95,
    embed_model=embed_model,
)

documents = SimpleDirectoryReader(input_files=["sample_document.txt"]).load_data()
nodes = splitter.get_nodes_from_documents(documents)

print(f"Split into {len(nodes)} chunks")
print(nodes[0].get_content())
buffer_size sets how many sentences get grouped before a similarity check – raise it and the chunker weighs wider context before deciding on a breakpoint, which smooths out noisy single-sentence outliers. breakpoint_percentile_threshold works like LangChain's percentile option: a value closer to 99 produces fewer, larger chunks, while a lower one produces more, tighter chunks that preserve less surrounding context per chunk. Tune both against a sample document from your own corpus rather than trusting the defaults – optimal chunk size for a legal contract and a chat transcript rarely match.
A few things worth doing before either of these goes into production: cache embeddings for chunks that don't change between runs, since recomputing them on every pipeline execution is where the additional computational cost of semantic chunking usually shows up. Attach metadata – source file, section heading, page number to each chunk so a retrieved result traces back to where it came from. And once the chunks are embedded and sitting in a vector database like Pinecone, Weaviate, or Chroma, run some real queries against it and check retrieval quality directly using evaluation metrics rather than a gut feeling; tools such as Ragas measure retrieval precision and answer relevancy, which is a more honest evaluation than eyeballing a few chunk boundaries and assuming they look reasonable.
Semantic chunking vs other chunking methods
Semantic chunking is one of several chunking strategies, and it isn't always the better choice over more traditional chunking approaches. Here's how it stacks up against the alternatives most RAG pipelines choose between.
| Method | How it splits | Compute cost | When it wins |
| Fixed size chunking | Cuts every N characters or tokens | Very low – no model calls | Large, uniform datasets |
| Recursive chunking | Splits by paragraphs, then sentences, then words | Low – no embedding model needed | Structured technical docs |
| Semantic chunking | Cuts at embedding-similarity boundaries | High – every sentence needs an embedding | Long-form, topically varied content |
| Hybrid chunking | Structure-aware split, then a semantic pass on overly large chunks | Medium | Production RAG at scale |
One caveat on fixed-size and recursive chunking: because both cut on structure rather than meaning, they can still split an idea across the document split point. Most production setups offset this with a sliding window technique – overlapping each chunk with a slice of its neighboring chunks, which helps with preserving context and contextual continuity even when the cut itself lands in an imperfect spot. Semantic chunking mostly sidesteps the need for overlap in the first place, since it aims to only cut between ideas rather than through them.
As a rule of thumb: lean on fixed-size or recursive chunking for structured technical documents where paragraph breaks already do most of the work, and save semantic chunking for long, loosely structured content where topic drift within the same document is the real problem hurting retrieval quality.
Is semantic chunking worth the computational cost?
The most direct answer comes from a 2025 study by Renyi Qu, Ruixuan Tu, and Forrest Bao, Is Semantic Chunking Worth the Computational Cost? (Findings of the Association for Computational Linguistics: NAACL 2025, arXiv:2410.13070). The researchers ran controlled experiments across document retrieval, evidence retrieval, and answer generation, comparing fixed-size chunking against two flavors of semantic chunker on the same datasets: a breakpoint-based semantic chunker that splits at semantic distance thresholds between consecutive sentences (the approach LangChain and LlamaIndex both implement), and a clustering-based semantic chunker that uses clustering algorithms to form topic-based chunks by grouping semantically similar sentences even when they aren't consecutive in the source text.
Their finding: across the tasks and datasets tested, the additional computational cost of semantic chunking wasn't consistently paid back in better retrieval or generation quality – the results were mixed enough that no chunking method won outright. When the underlying embedding model was already strong, the choice of chunking strategy mattered less than expected: fixed-size chunking sometimes matched or beat semantic chunking, and the clustering-based semantic chunker underperformed the other two in several evaluation runs. Chunking, it turns out, is a smaller lever on retrieval-augmented generation systems' overall accuracy than embedding quality is.
That doesn't make semantic chunking pointless. It means the payoff depends on your documents and your embedding model, not on a universal rule. Long-form, topically diverse input documents (research reports, meeting transcripts, wikis that mix subjects on the same page) are where the experiments still found semantic chunking pulling its weight. Documents that are already well-structured with consistent headings, short sections, one topic per page – get most of the same benefit from recursive chunking on document structure alone, for a fraction of the compute. The same trade-off shows up in more complex agentic search and agentic RAG pipelines, too: a grader agent deciding whether retrieved context is good enough has an easier job when the chunks it's judging are already topically clean.
For the full methodology and results, paper on arXiv, the published version in ACL Anthology, or Vectara's summary of the findings.
Wrapping up
Semantic chunking solves a real problem: fixed-size chunks that split an argument in half and confuse retrieval. But it isn't free, and it isn't always necessary. Start by checking whether your document structure already gives you clean boundaries – if headings and paragraphs do the work, recursive chunking is cheaper and nearly as good. Reach for a semantic chunker when documents are long, loosely structured, and the cost of pulling in the wrong context outweighs the cost of an extra embedding call per sentence.
Whichever chunking method you land on, chunk quality only ever matches the quality of what goes in. The semantic search tools setup picking through fragmented, boilerplate-heavy web pages will struggle no matter how cleanly the text gets split afterward. If you're assembling the input documents for a RAG pipeline straight from the web, structured extraction that hands back clean Markdown like Oxylabs' Web Scraper API removes a lot of the cleanup that would otherwise show up as noise in your chunks.
Frequently asked questions
What is semantic chunking?
Semantic chunking is a method for splitting text into chunks based on meaning rather than a fixed character or token count. A semantic chunker measures the semantic similarity between sentences and only creates a new chunk when the topic changes, so each resulting chunk stays semantically coherent instead of cutting an idea in half.
Is semantic chunking worth it?
What are different types of chunking?
Which Python libraries support semantic chunking?
About the author
Shinthiya Nowsain Promi
Technical Content Researcher
With a background in Computer Science, Shinthiya likes to turn technical jargons into clear, perspective-driven writing that rewards a reader's time rather than wasting it.
All information on Oxylabs Blog is provided on an "as is" basis and for informational purposes only. We make no representation and disclaim all liability with respect to your use of any information contained on Oxylabs Blog or any third-party websites that may be linked therein. Before engaging in scraping activities of any kind you should consult your legal advisors and carefully read the particular website's terms of service or receive a scraping license.
Related articles

Eliminate the complexity of web scraping
Explore Oxylabs' AI Studio for automated data scraping using natural language prompts.

Get the latest news from data gathering world
Scale up your business with Oxylabs®
Proxies
Advanced proxy solutions
Data Collection
Datasets
Resources
Innovation hub
Eliminate the complexity of web scraping
Explore Oxylabs' AI Studio for automated data scraping using natural language prompts.