99.9%
API uptime, backed by high success rates and fast response time.
Reliable retrieval at scale on the toughest targets, from JS-heavy pages to complex sites. Every request comes back as clean, ready-to-use data.
Trusted by 15,000+ clients globally:


Reliable extraction from any public site
Retrieve web data from any public page at scale – CAPTCHA and JS rendering handled to succeed even on tough sites.
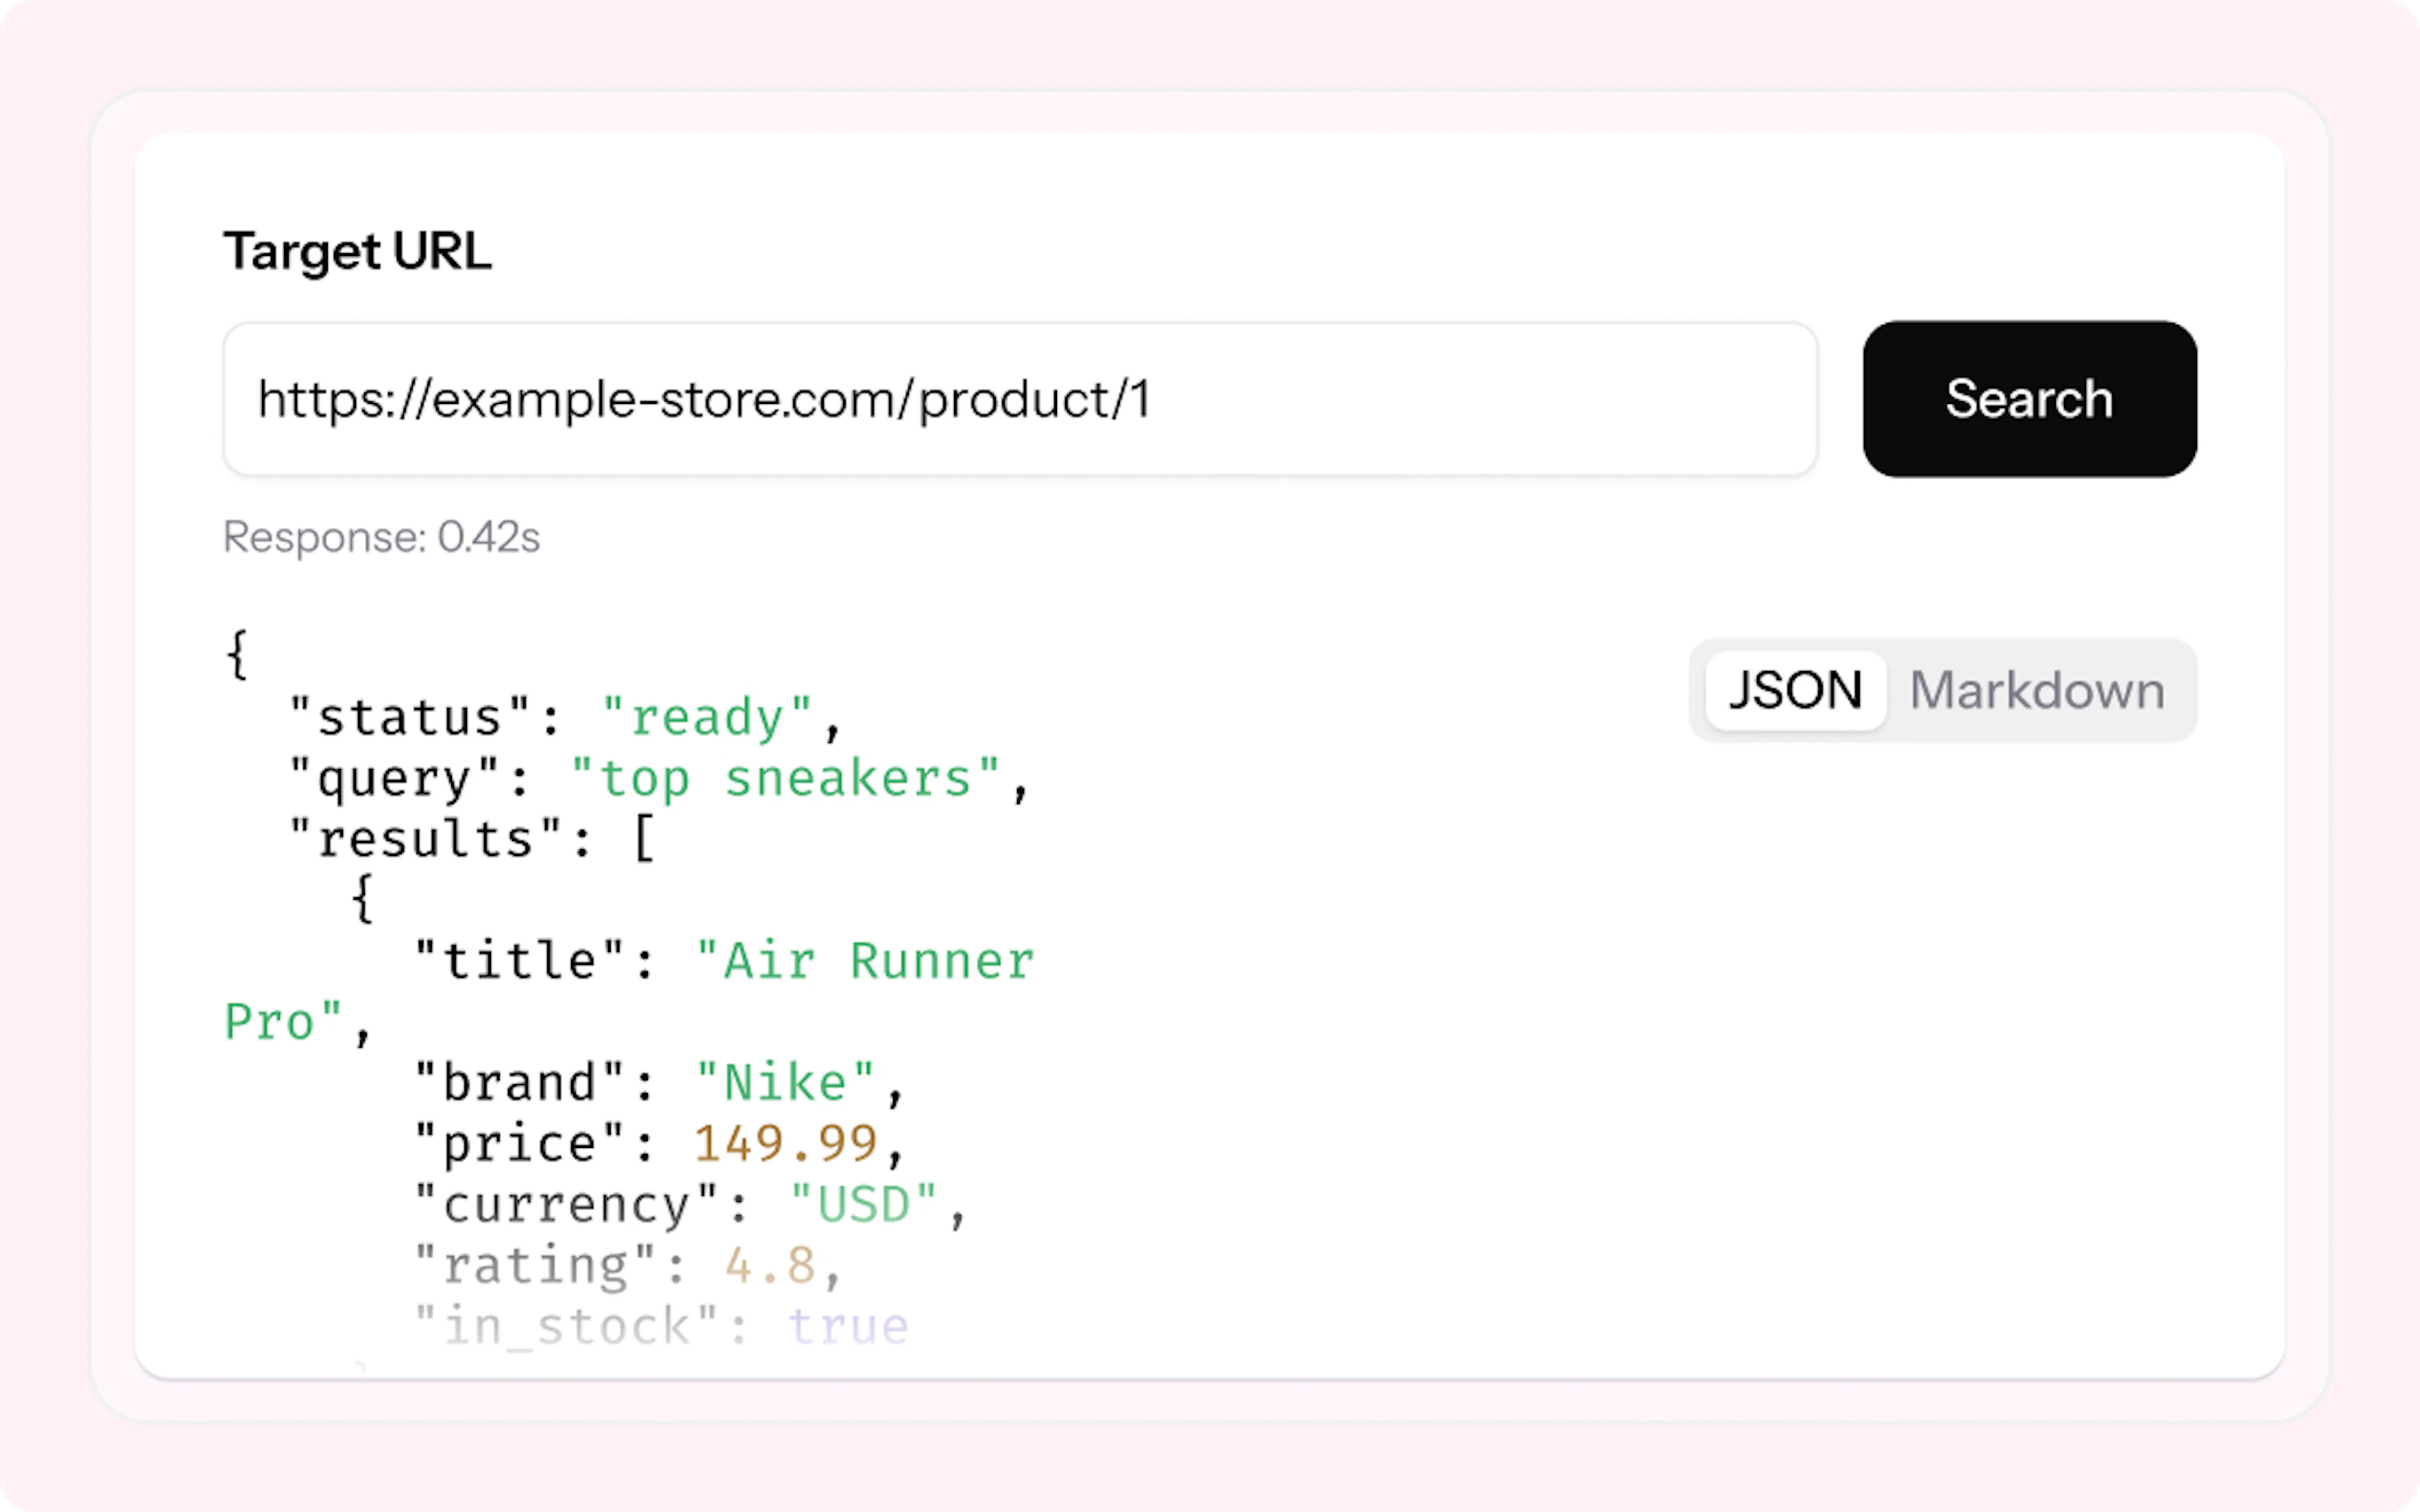
Structured data from popular targets
Get ready-to-use data from popular targets like Google, Amazon, and Walmart, including target-specific parameters for clean output.
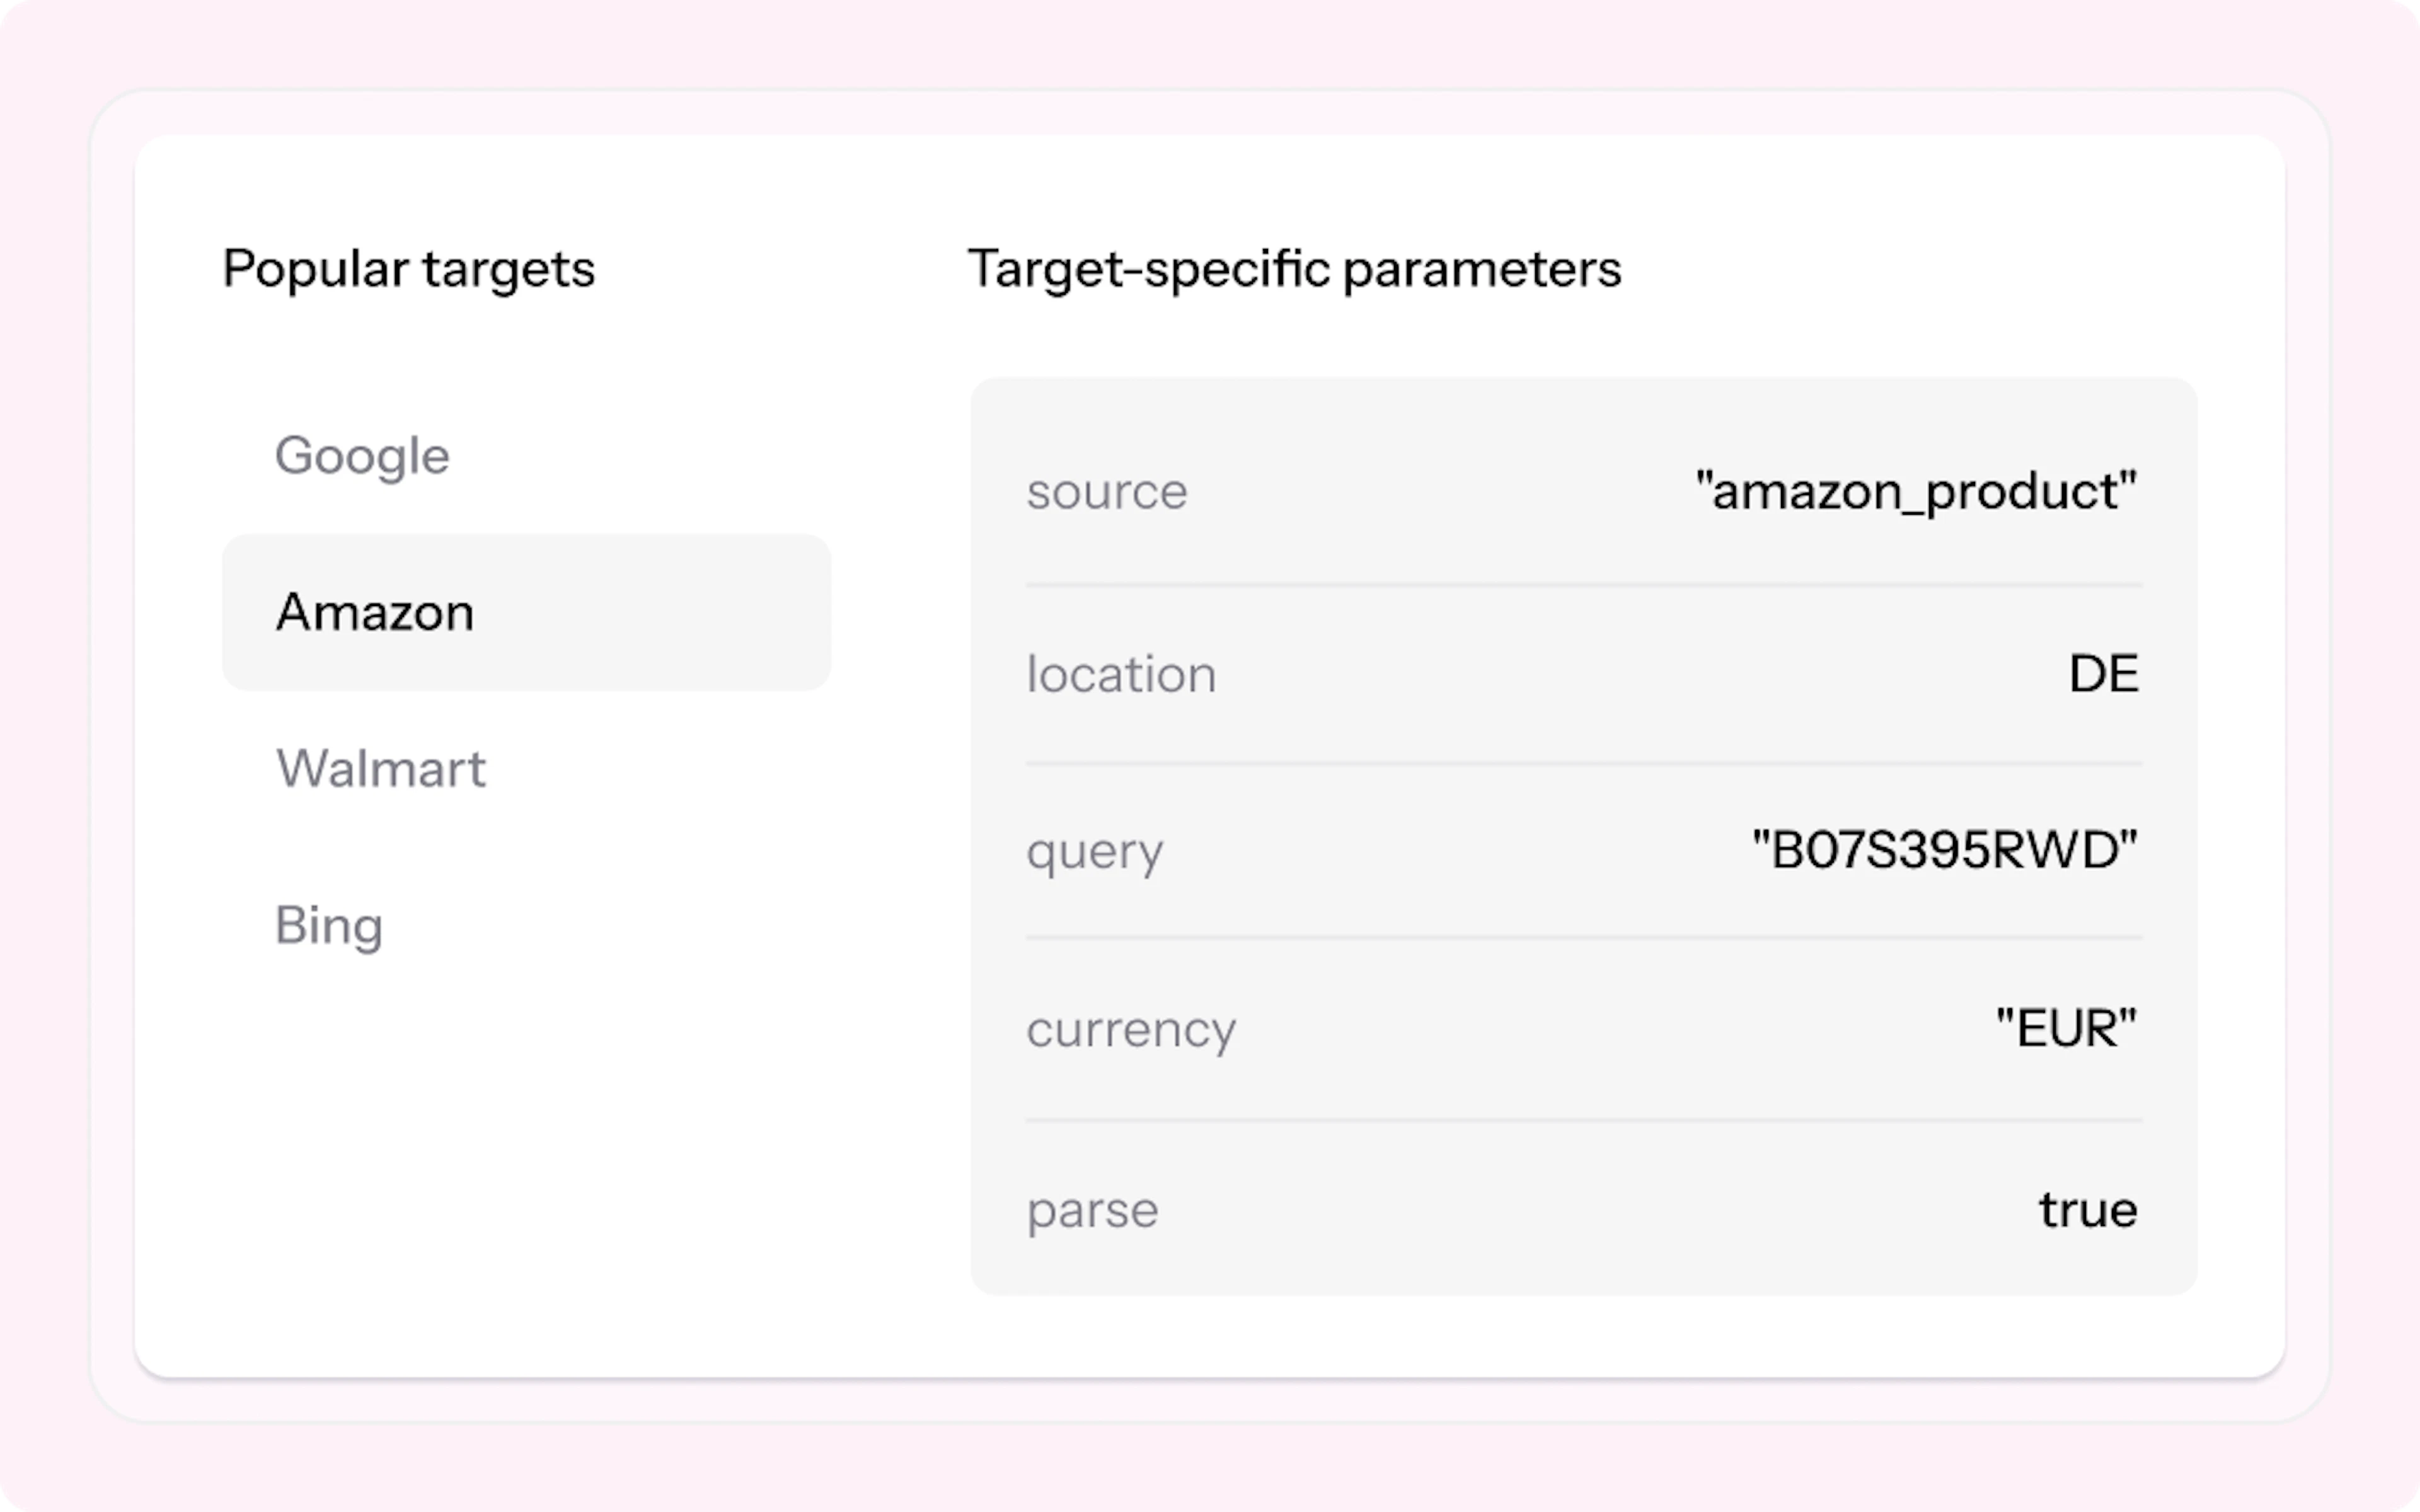
High-volume workloads
Handle any request load – keep high success rates and production-grade concurrency reliable as your volume grows.
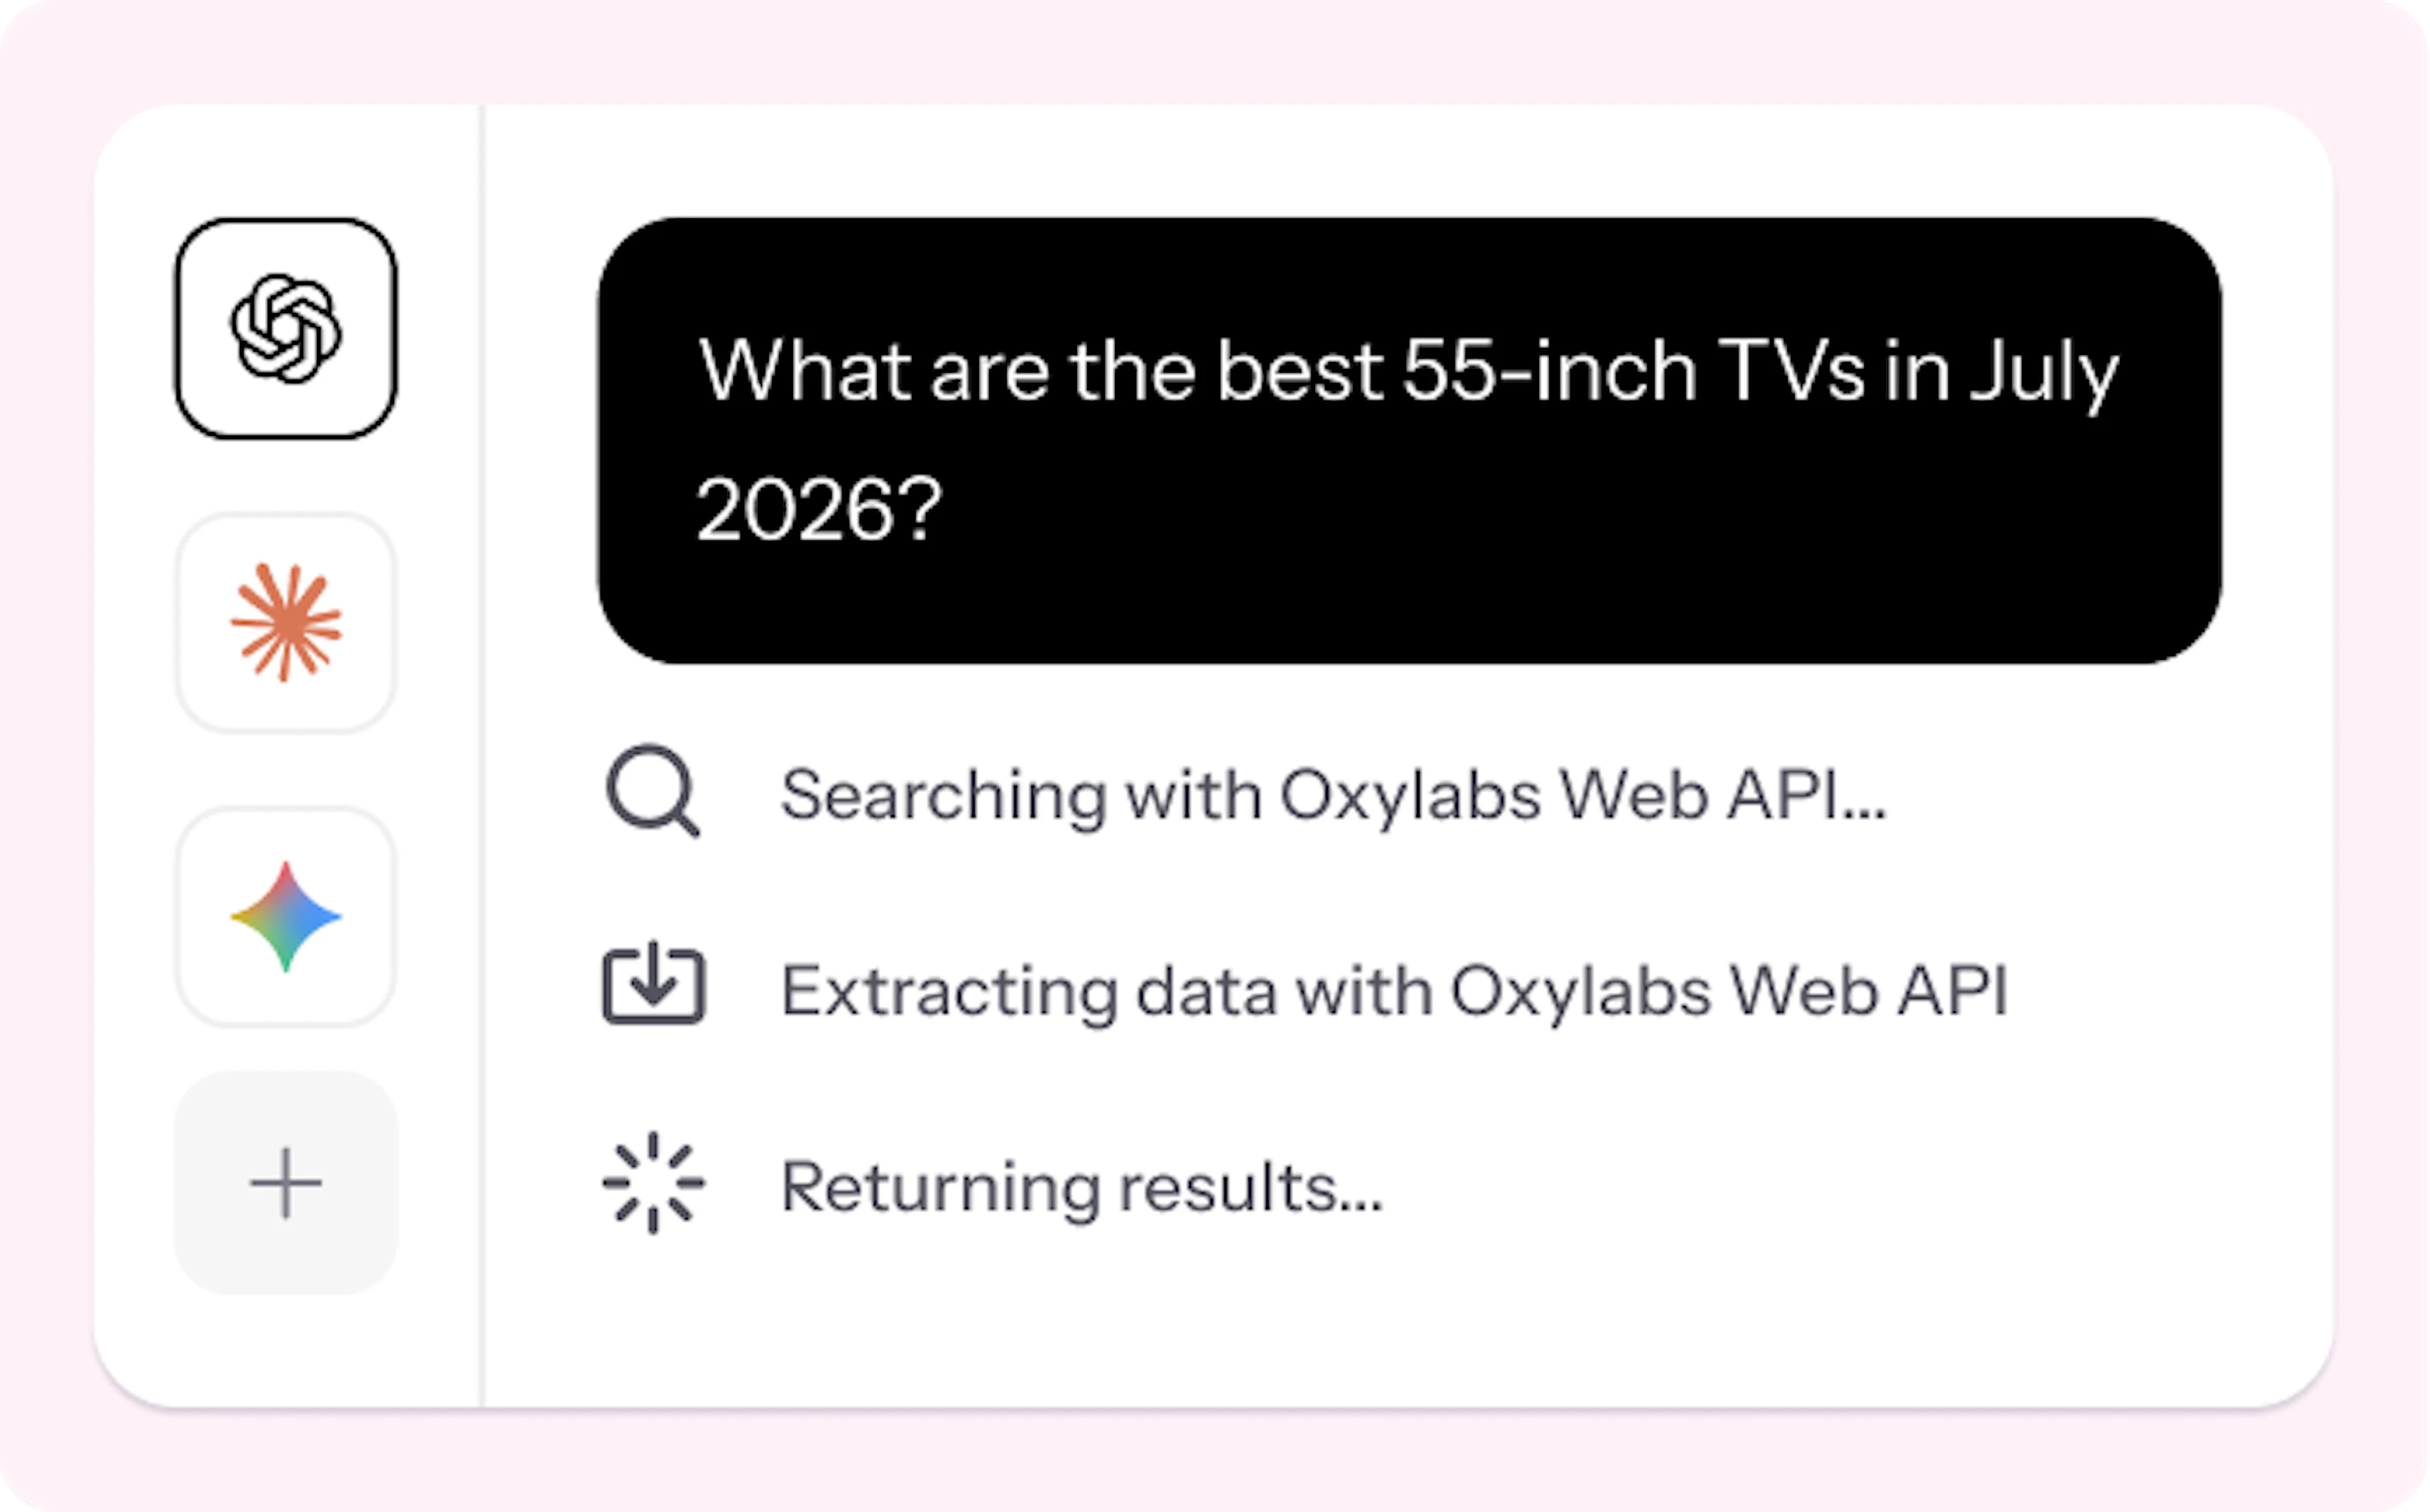
Agent-native by design
Connect agents from the ground up – with MCP, Agent Skills, and token-efficient output on the same key you use for Search.
Enterprise-grade scraping infrastructure
Run on certified, dependable infrastructure. Backed by round-the-clock support and over a decade of production expertise.
Retrieve web data from any public page at scale – CAPTCHA and JS rendering handled to succeed even on tough sites.
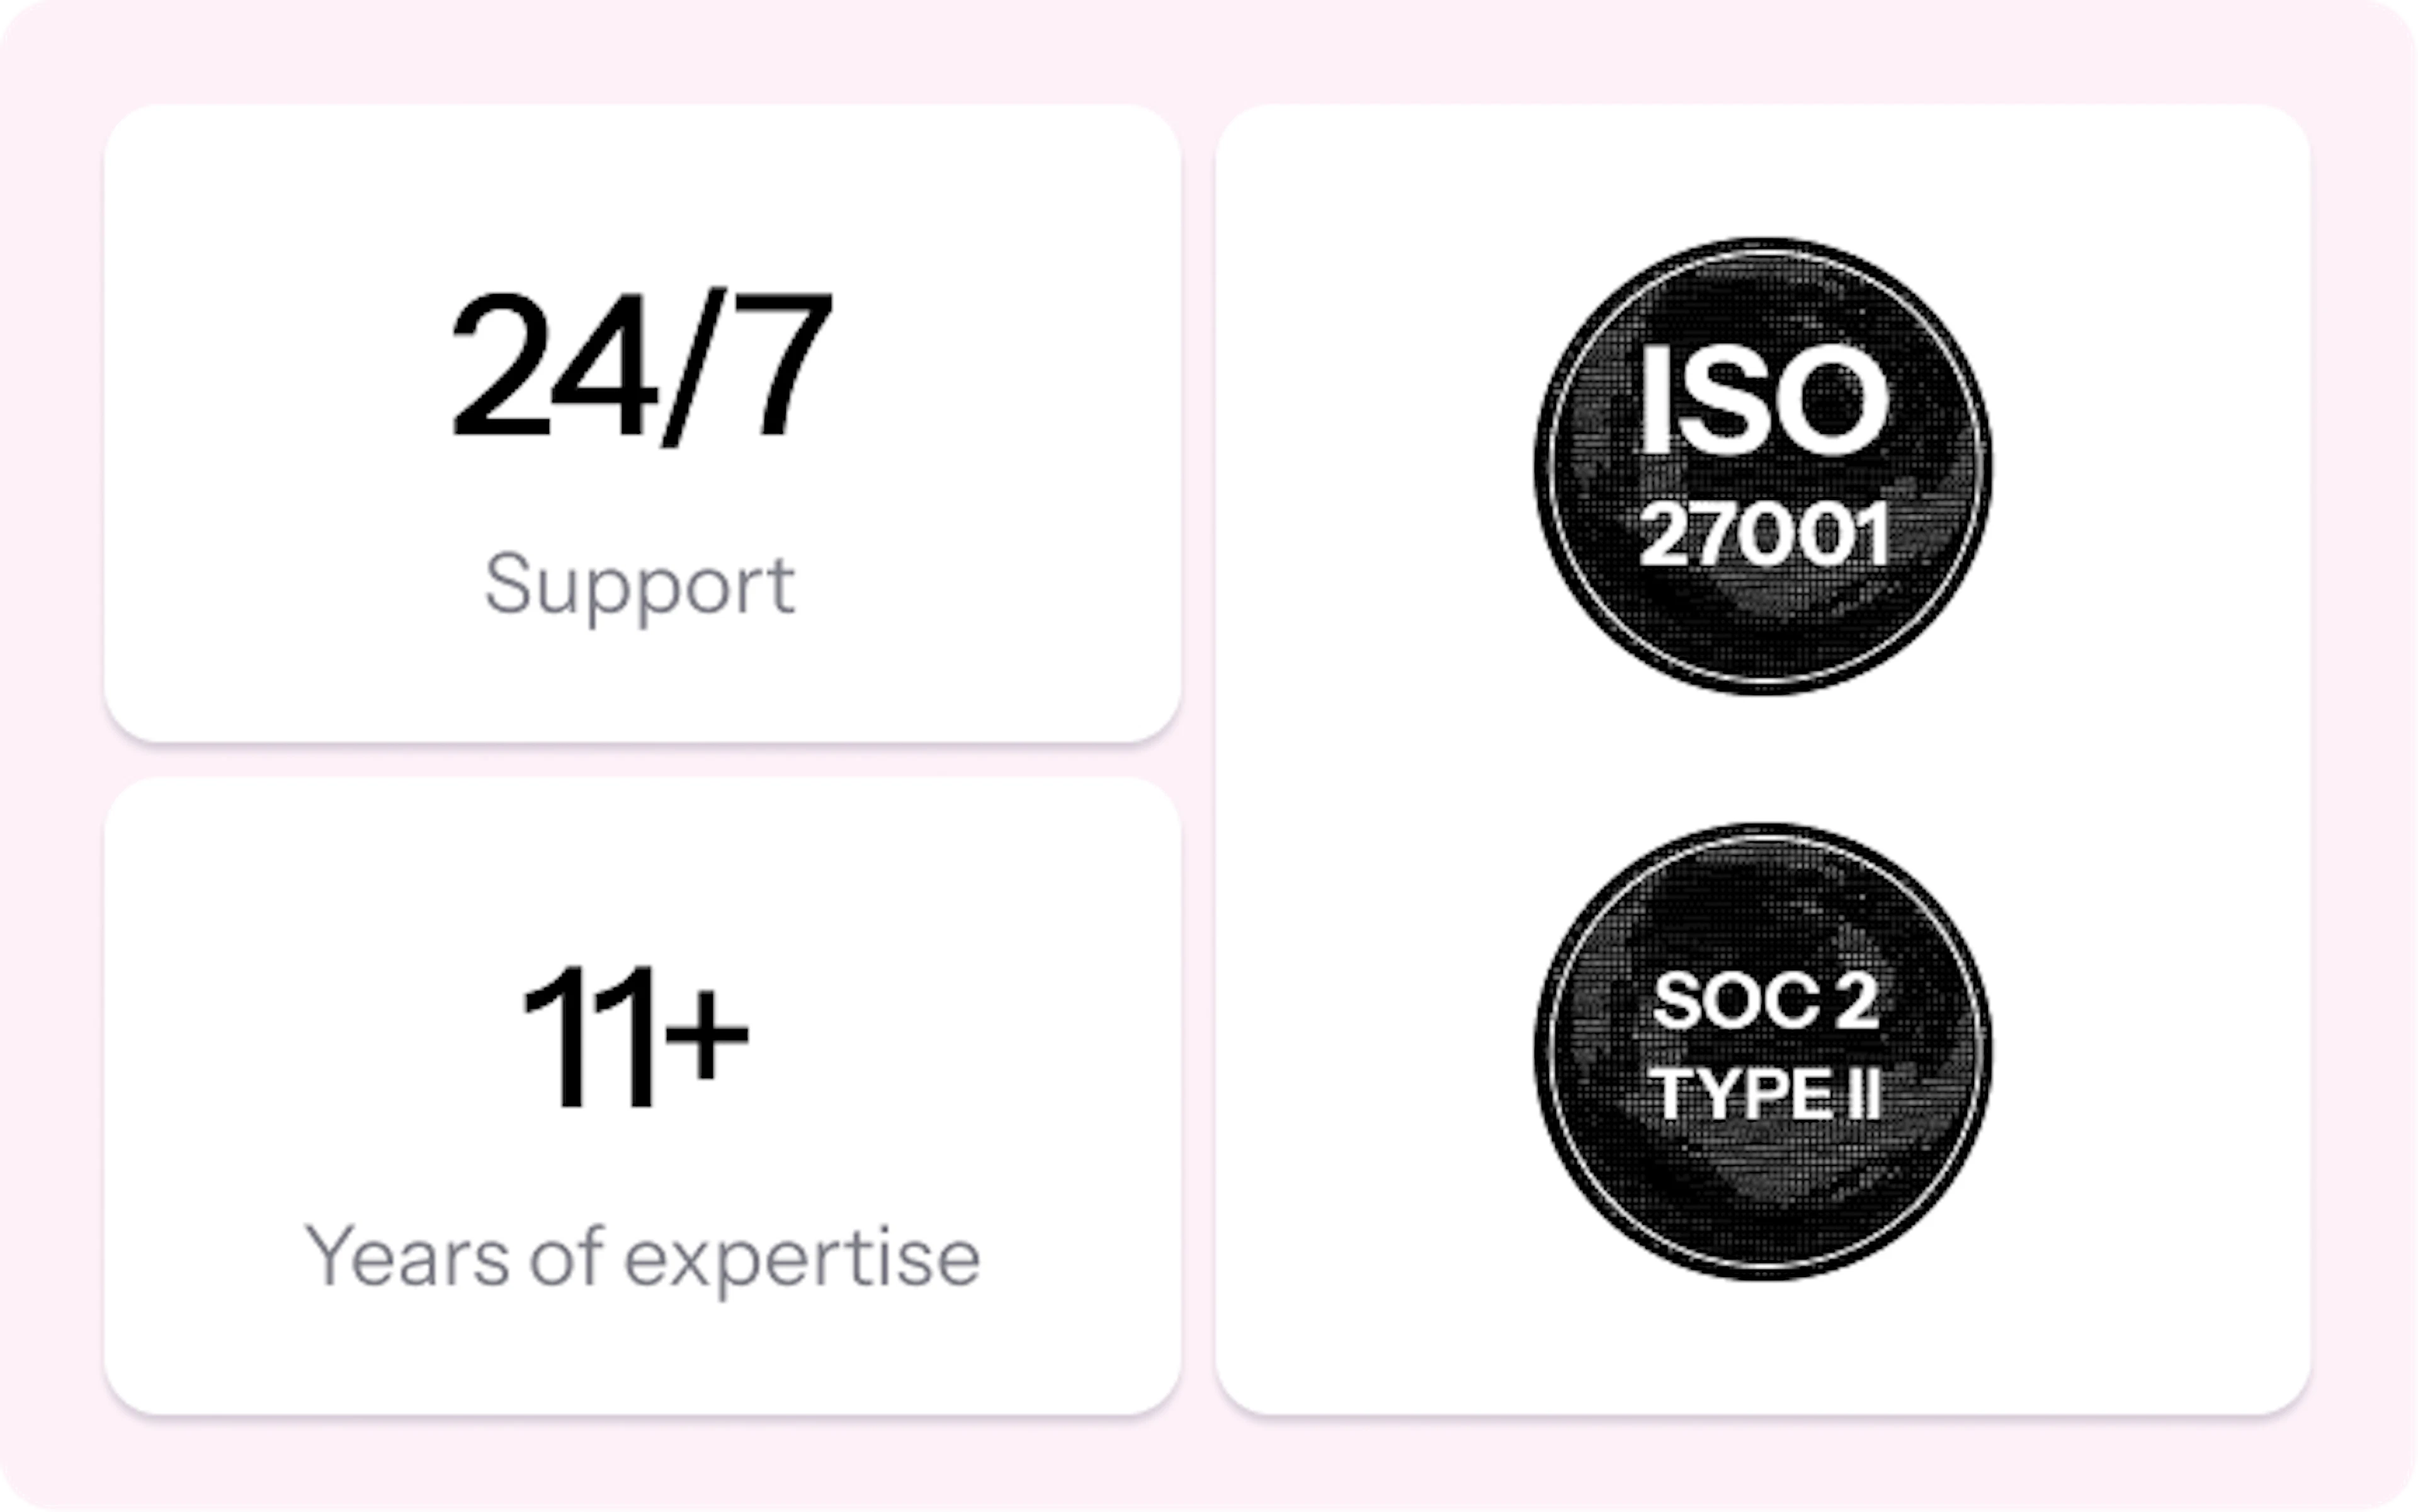
API uptime, backed by high success rates and fast response time.
Years of expertise, returning data consistently regardless of request volume.
Proxies across 195 countries for accurate data from any region.
Single subscription. All product access.
Welcome credits
FREE
Starter
$30/mo
Basic
$100/mo
Flexible
$500/mo
Enterprise
Custom
/Scrape
From
$0.50/1K res.
Up to 10K results
From
$0.50/1K res.
Up to 60K results
From
$0.45/1K res.
Up to 222K results
From
$0.35/1K res.
Up to 1.43M results
From
$0.25/1K res.
10M+ results
Can't find the plan that suits your business case? Explore more options
Industry-leading success rates
24/7 expert support
Enterprise-grade security & compliance
Real-time spending & usage data
Fast-adapting infrastructure
Scaling with your needs
"Oxylabs offered one of the best price-to-value combinations in the market and helped us save our total web scraping costs."
Wei Zheng
Chief Product Officer
“It’s given us peace of mind that we have a reliable solution that we are certain can scale into the future.”
Andrew Mabbott
Head of Development

“Oxylabs met all three of our requirements: fair pricing, fast response time, and high success rate.”
Dennett Ingram
Chief Executive Officer
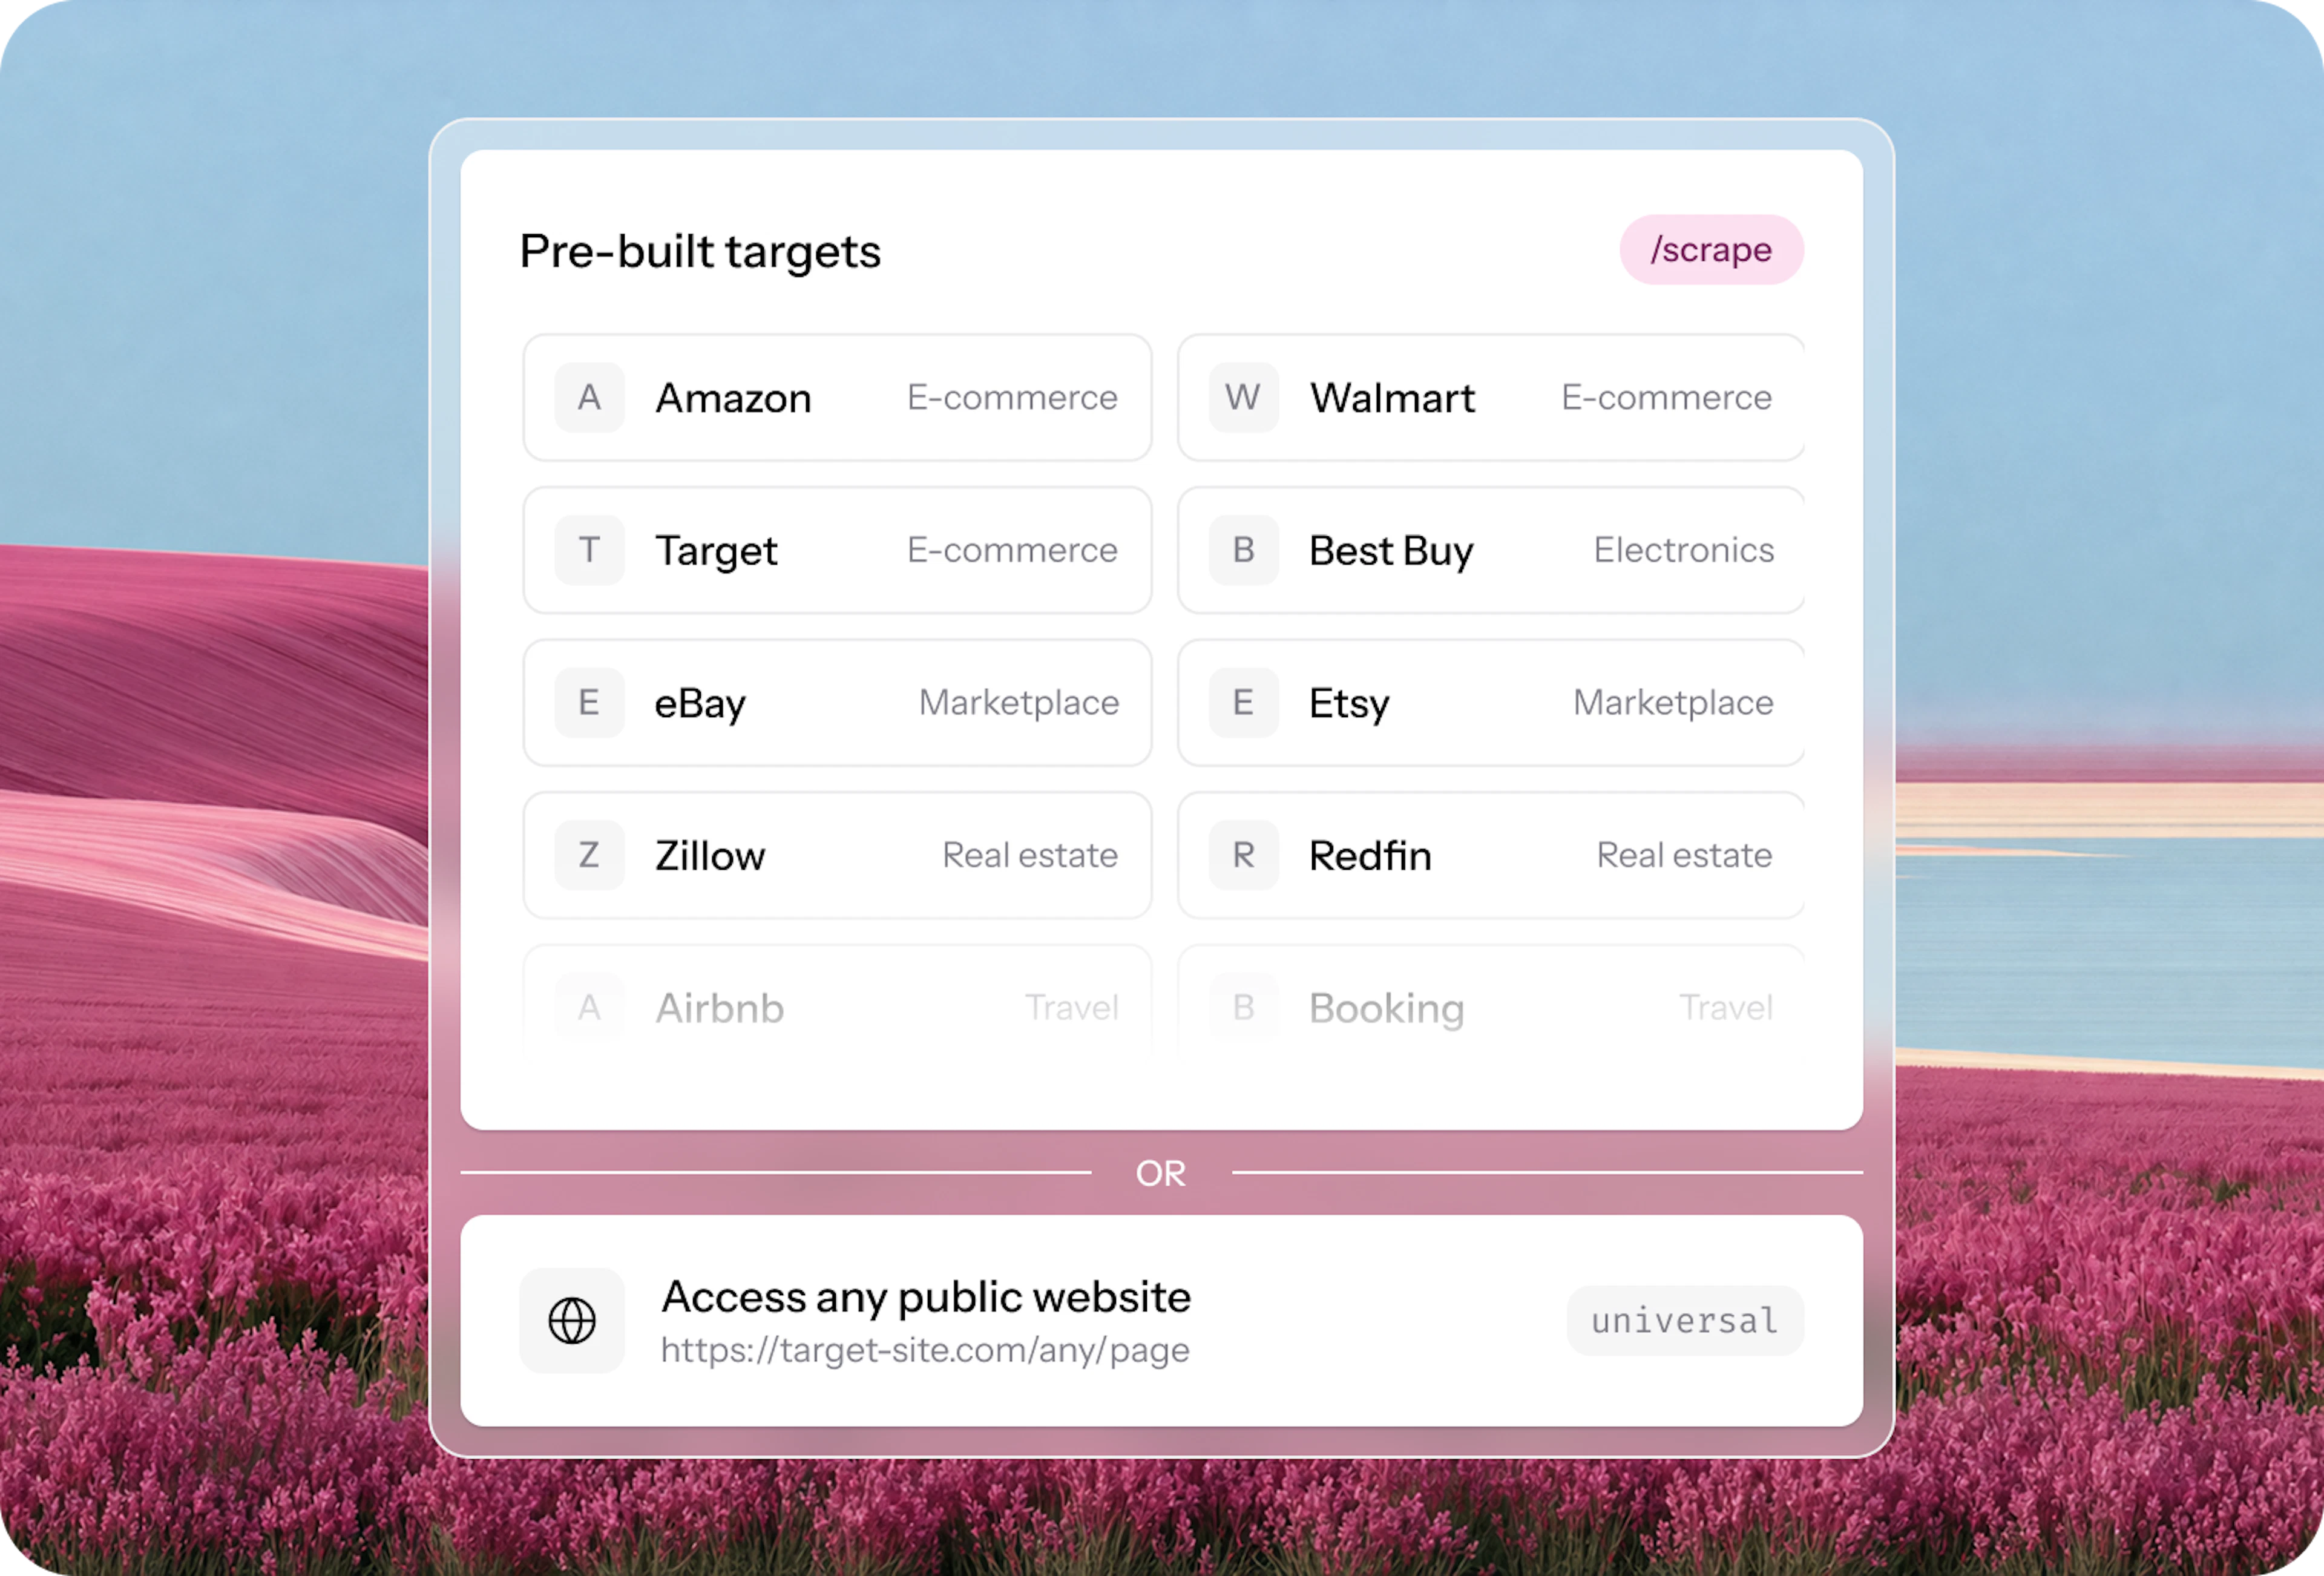
Pre-configured sources make popular websites easy to reach, with live data handed back ready to use. And you're not limited to them: retrieve public data from across the whole public web, with the same reliability.
Built to work instantly
Skip the setup and upkeep – each target comes pre-configured, so you can start collecting data immediately.
Maximum flexibility
Shape each request with customizable parameters like location, language, custom headers, and more.


MCP Server and Agent Skills for instant agent access.
Starts from
$0.25/1K results
The standard for robust risk assessment and information security, covering our Datacenter Proxies, Residential Proxies, and Web API solutions.
The audit report covers controls relevant to Security, Availability, and Confidentiality across Oxylabs' Scrape endpoint & Web Unblocker solutions.
Information security is embedded in Oxylabs' governance, with a certified management system and controls covering our operations and products.
Scrape endpoint retrieves clean, structured content from the pages you already know – powering the workflows teams run at scale, from grounding agents to tracking competitors.
Agent grounding & RAG
Feed AI applications clean, structured content retrieved in full and ready for context or indexing.
Enterprise research automation
Retrieve content for analysis-ready reports across banking, consulting, and M&A.
Competitive & market intelligence
Monitor pricing pages, changelogs, docs, reviews, and more. Catch market shifts as they happen.
E-commerce & product intelligence
Extract product information for continuous repricing, MAP, and digital-shelf tracking.
AI model & training data
Build and refresh training datasets with a data extraction that holds up under production load.
Monitoring & risk intelligence
Retrieve documents and monitor pages – turn filings and regulatory updates into structured, timely alerts.
Find answers to the most common questions about Web API, /scrape endpoint, and how it works.
The Web API Scrape endpoint supports multiple output formats so you can use the data however you need. You can receive raw HTML, clean Markdown, or parsed, structured JSON – and even a screenshot of the page. This flexibility lets you send data straight into automated workflows, LLMs, or data pipelines without extra processing.
Yes. Many modern sites load content dynamically, so our Scrape endpoint can enable JavaScript rendering to capture that dynamic content. This means you get complete data from JavaScript-rendered pages – not just the initial HTML – so nothing important is missed on interactive or content-heavy sites.
Many web scraper APIs return raw HTML you still have to clean and maintain – and some rely on cached data that's already out of date. Oxylabs' Web API pulls from the live web on every request, so you always get the freshest, real-time data. It combines /search and /scrape under one API key, with /scrape delivering clean data in structured formats, all backed by premium proxies and enterprise-grade infrastructure that holds up at scale.
Yes. Web API is agent-native by design. It offers MCP and Agent Skills so AI agents can access live web data directly, and returns token-efficient, structured data that LLMs can reason over. This makes it easy to give agents fresh data and search results from the live web through a single access layer.
A web scraping API is a tool that collects data from websites and returns it in a structured, ready-to-use format. Instead of writing and running your own web scraper, you make an API call with your parameters, and the API handles fetching the page, JavaScript rendering, and proxy rotation for you – then delivers clean, structured data.
You send a request to the API (usually specifying a target website and your parameters) authenticated with your API key. Behind the scenes, the scraping API fetches the page, handles proxy management and JavaScript rendering, and extracts the content. It then returns the result in structured formats like JSON, so you can feed it straight into your data pipelines.
Building your own scraper means maintaining proxies, handling JavaScript-rendered pages, fixing failed requests, and adapting to constant site changes. A web scraping API takes care of all of that as a cloud-based service. You get more successful requests, faster setup, and reliable large scale data extraction – without the ongoing upkeep of running scraping tools yourself.
A scraper fetches the content – it retrieves the raw HTML from a target website. A parser interprets it – turning that raw HTML into structured, usable data. In simple terms: the scraper gets the page, and data parsing extracts the specific fields you need, like prices, product listings, or contact details, into a clean, structured format.
The best web scraping APIs combine reliability, coverage, and clean output. Look for a high rate of successful results even on complex sites, built-in JavaScript rendering, proxy rotation, and flexible output formats. Strong bulk request handling, clear documentation, and dependable infrastructure are what set a production-ready service apart from basic scraping tools.
Focus on reliability and ease of use. A good web scraping API should handle proxy management and JavaScript rendering for you, return data in structured formats, and scale from small tests to large scale data extraction. Also check for a flexible API, fair pricing or API credits, and good support – so the service grows with your needs.
There's no one-size-fits-all answer. Whether a scraping project is lawful depends on how the data is collected and used. Oxylabs requires customers to collect only publicly available data and to comply with all other terms of our Acceptable Use Policy. Oxylabs promotes ethical scraping and shares general educational resources on the topic, but consult with your legal advisor before any scraping project to avoid any potential risks.
Tell us what you need – get clean, structured public web data back.